TRL
Hugging Face library for training language models with RLHF, SFT, and DPO
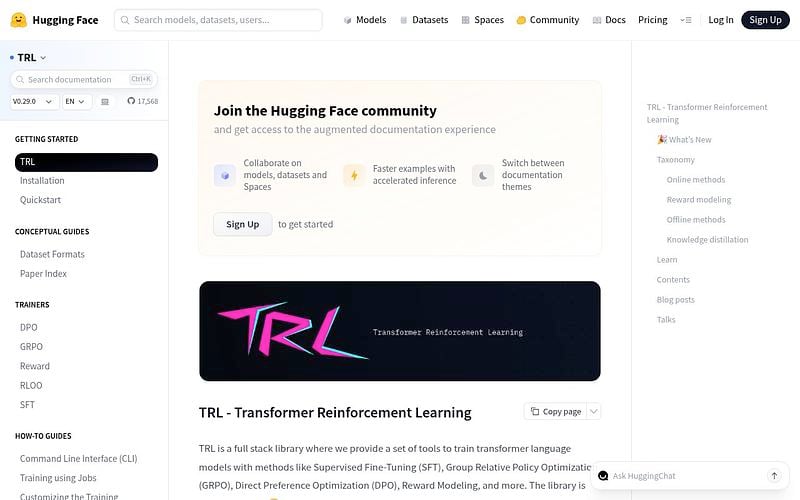
TRL (Transformer Reinforcement Learning) is the standard Hugging Face library for fine-tuning language models. It supports supervised fine-tuning (SFT), reinforcement learning from human feedback (RLHF), direct preference optimization (DPO), and other alignment techniques. Built on top of Transformers and integrates with PEFT for parameter-efficient training.
Pricing: Free
Choosing a fine-tuning platform right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing a fine-tuning platform right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
TRL Alternatives
Explore 20 products in the Fine-tuning category. View all TRL alternatives.

LLaMA-Factory
Open-source fine-tuning framework for 100+ LLMs with a web UI

torchtune
PyTorch-native fine-tuning library from Meta, no longer actively maintained (development wound down in 2025)

Axolotl
Open-source toolkit for fine-tuning LLMs with a single YAML config across the full training pipeline
OVHcloud AI
European cloud provider with AI inference, training, and deployment services
Amazon Bedrock
Managed API access to foundation models on AWS with built-in fine-tuning and agent tooling
Work on TRL? Feature it at the top of Fine-tuning.
Is your product missing?