Foundry Local
Microsoft's on-device AI runtime and SDK that runs ONNX models on the user's NPU, GPU or CPU
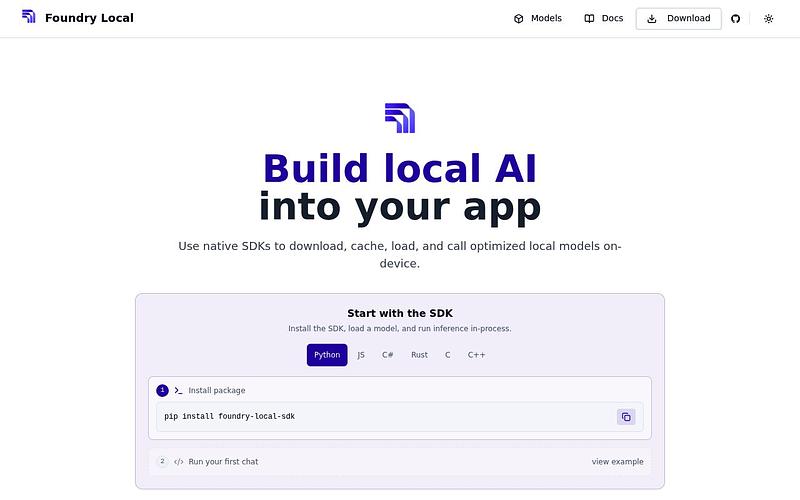
Foundry Local is Microsoft's on-device inference runtime, built to ship inside an application rather than run as a shared server. It runs models through ONNX Runtime and picks an NPU, GPU or CPU execution provider automatically.
It supports Windows, macOS (Apple silicon) and Linux, with SDKs for C, C++, C#, JavaScript, Python and Rust, an optional OpenAI-compatible local server and a CLI. Models come from a curated catalog (Qwen, Phi, Mistral, GPT OSS, Whisper) or your own ONNX Runtime GenAI models.
The SDK is MIT licensed; the CLI is a preview under Microsoft license terms.
Pricing: Free
Choosing a local LLM runtime right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing a local LLM runtime right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Foundry Local Alternatives
Explore 49 products in the Frameworks & Stacks category. View all Foundry Local alternatives.
GPT4All
Desktop app and Python SDK for running open-source LLMs locally on any device
LocalAI
Open-source, self-hosted OpenAI-compatible API for running models on your own hardware
Jan
Open-source desktop app for running LLMs locally with a clean GUI

Lemonade Server
Local AI server for LLMs, speech and images, tuned for AMD Ryzen AI NPUs and Radeon GPUs
TextGen
Formerly text-generation-webui: open-source desktop app and web UI for local LLMs with an OpenAI-compatible API
Dify
Easily build and operate generative AI applications. Create Assistants API and GPTs based on any LLMs.
Work on Foundry Local? Feature it at the top of Frameworks & Stacks.
Is your product missing?