AI Gateway HQ
LLM gateway built around spend limits enforced before a request reaches a provider
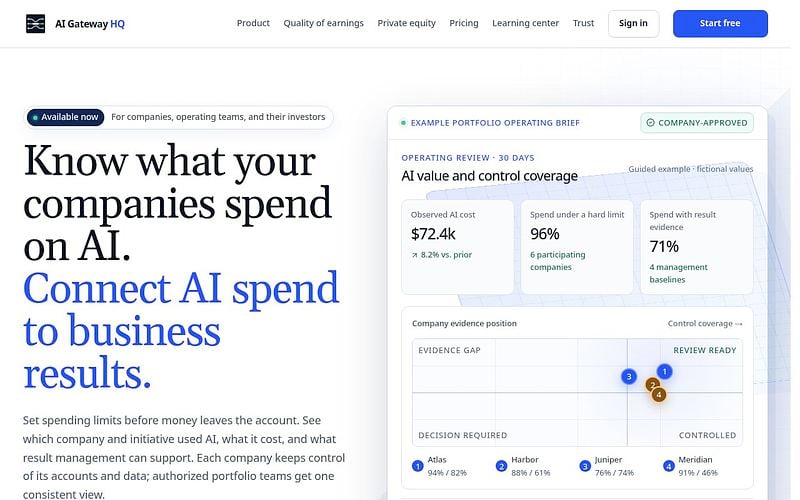
AI Gateway HQ sits between applications, coding agents and automations and the model providers behind them, routing each request to an approved model and moving to a compatible backup when one is slow, unavailable or over budget.
The distinguishing feature is that budgets are enforcement rather than reporting. Every eligible request reserves its ceiling before a provider can charge, organisation and workload limits sit next to their hard-stop behaviour, and new provider attempts stop at the cap with automatic reload off until separately authorised.
Providers covered include OpenAI, Anthropic, Bedrock and Gemini. Bring-your-own-key usage is billed at the customer own provider rates with no inference markup; the gateway fee is charged separately.
A no-card Test Lab runs policy logic without connecting a provider. Paid tiers run from $0.10 per 1,000 successful requests on prepaid Flex, through Company at $499/month for 2M requests with OIDC, SAML and SCIM, to a Portfolio tier at $1,500/month aimed at private-equity sponsors reporting across portfolio companies.
AI Gateway HQ Alternatives
Explore 100 products in the Inference APIs category. View all AI Gateway HQ alternatives.

Varion
OpenAI-compatible proxy that trims LLM token usage before requests reach your provider
AISIX
Open-source AI gateway in Rust with one OpenAI-compatible API across 100+ LLM providers
2kw.ai
EU-hosted AI integration platform combining a provider gateway, document extraction, evals and cost observability
Also listed in
Work on AI Gateway HQ? Feature it at the top of Inference APIs.
Is your product missing?