ParalonCloud
GPU marketplace billed by the minute, plus an OpenAI-compatible API for open models
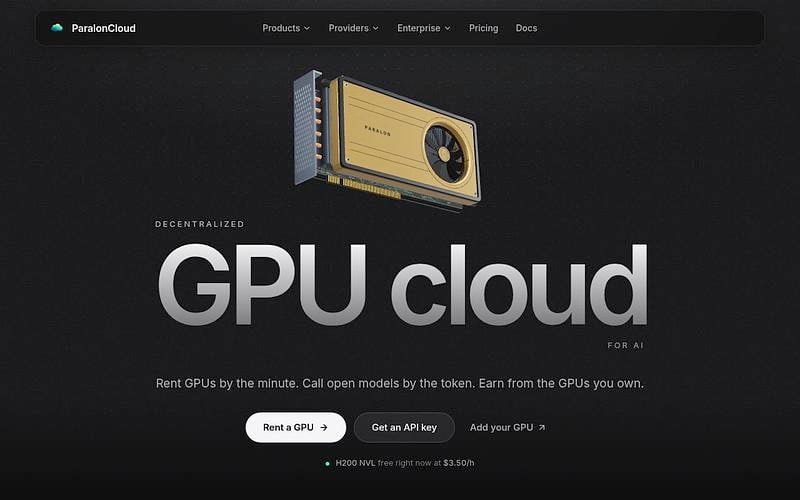
ParalonCloud is a GPU marketplace where independent providers rent out their machines and developers rent them by the minute, with JupyterLab, SSH or a ready app such as ComfyUI. Machines range from an RTX 4090 to an H200 NVL, and each listing shows measured speed and network scores.
The same network runs an OpenAI-compatible inference API for open models (chat, embeddings and image generation), priced per million tokens with 50% off batch requests. Requests run on provider-owned machines that may be in any country; the privacy policy says prompts and outputs are not stored.
Pricing: Pay-as-you-go
Data and privacy
Checked 20 November 2026- Data processed
- On GPUs owned and operated by independent providers, which may be in any country source
- DPA
- Not public
- Sub-processors
- Not public
- US parent company
- No
Read from ParalonCloud's own legal pages. "Not public" means it is not on their site; some providers share it on request.
Choosing a GPU cloud right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing a GPU cloud right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
ParalonCloud prices by model
Per 1M tokens, read off ParalonCloud's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| Qwen3.8 27B | $0.14 | – | $2.00 | 20 Nov 2026 | Batch API 50% off ($0.07 / $1.00) |
ParalonCloud Alternatives
Explore 173 products in the Inference APIs category. View all ParalonCloud alternatives.

CoreWeave
GPU cloud infrastructure built for large-scale AI training and inference workloads
AiQu
Swedish GPU infrastructure and LLM hosting platform with API-first deployment, no Kubernetes required

Hetzner GPU Servers
Dedicated single-GPU servers with NVIDIA RTX PRO Blackwell cards, billed hourly, in Finland and Germany
Inferbase
AI gateway with policy routing, fallback, guardrails and logs, on your own provider keys or managed models

Work on ParalonCloud? Feature it at the top of Inference APIs.
Is your product missing?