evalship
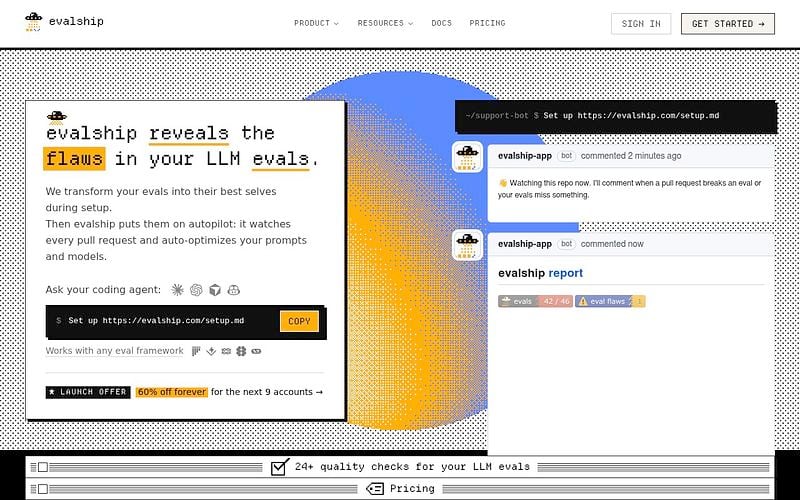
Reviews your LLM evals for flaws and comments on pull requests that break them
evalship checks the quality of LLM evals rather than running them. It reviews an existing eval suite for flaws, such as a judge that scores a case 1.0 when the judge call fails, and flags AI calls in the code that have no eval.
Once connected to a GitHub repository it comments on pull requests, separating real regressions from flaky cases by comparing recent runs on the main branch. It works with existing eval frameworks and keeps eval history for 30 days to 2 years depending on the plan.
The Free plan covers public repositories and one private repository. Paid plans start at $19/month. It is run by Garm Tech B.V. in Amsterdam.
Pricing: Monthly / yearly subscriptions
Choosing an LLM evaluation tool right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing an LLM evaluation tool right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
evalship Alternatives
Explore 62 products in the Observability & Analytics category. View all evalship alternatives.

Braintrust
Stop building AI in the dark.
Lunary
The platform to monitor, manage and improve your LLM apps.
Langfuse
Traces, evals, prompt management and metrics to debug and improve your LLM application.
Work on evalship? Feature it at the top of Observability & Analytics.
Is your product missing?