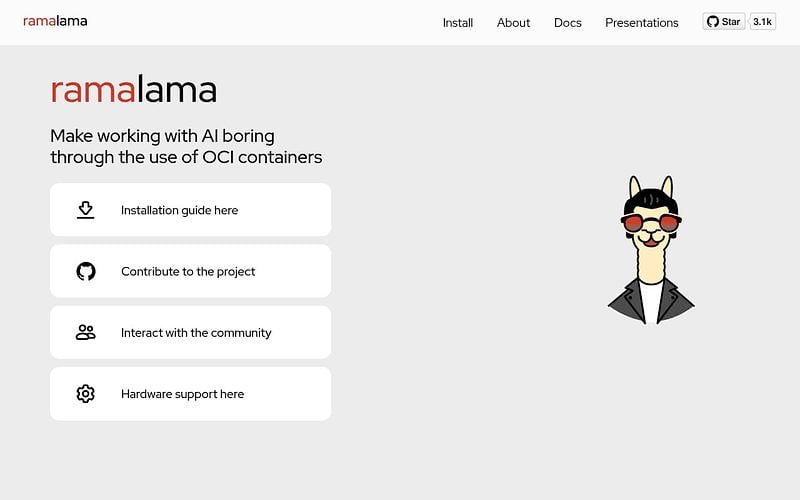
RamaLama
Run and serve local LLMs in GPU-matched OCI containers with Podman or Docker
RamaLama is a CLI from the containers project, home of Podman, that runs and serves models inside OCI containers. On first run it detects the GPU and pulls a matching image for CUDA, ROCm, Vulkan, Intel, Apple Silicon or Ascend, falling back to CPU.
Models come from Hugging Face, ModelScope, Ollama or any OCI registry and are managed like container images. Its serve command starts llama.cpp's HTTP server by default, with vLLM and MLX as alternative runtimes. Runs on Linux, macOS and Windows via WSL2. MIT licensed.
Pricing: Free
Choosing a local LLM runtime right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing a local LLM runtime right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
RamaLama Alternatives
Explore 49 products in the Frameworks & Stacks category. View all RamaLama alternatives.
GPT4All
Desktop app and Python SDK for running open-source LLMs locally on any device
LocalAI
Open-source, self-hosted OpenAI-compatible API for running models on your own hardware
Jan
Open-source desktop app for running LLMs locally with a clean GUI

Docker Model Runner
Run and serve local LLMs from Docker Hub or Hugging Face with docker model commands and an OpenAI-compatible API
Foundry Local
Microsoft's on-device AI runtime and SDK that runs ONNX models on the user's NPU, GPU or CPU

Lemonade Server
Local AI server for LLMs, speech and images, tuned for AMD Ryzen AI NPUs and Radeon GPUs
Work on RamaLama? Feature it at the top of Frameworks & Stacks.
Is your product missing?