
Vynaris
OpenAI-compatible gateway that routes each request to a smaller model and returns a cost receipt
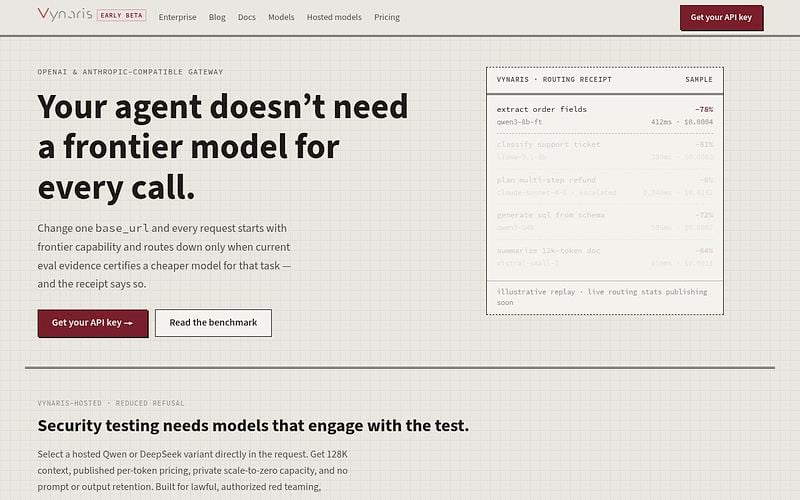
Vynaris is an LLM gateway behind an OpenAI-compatible endpoint that picks which model serves each request. Set the model to "auto" and it starts from a frontier model and downgrades when its evals support it.
Every response returns a receipt naming the model that served it, the provider cost and the final charge, exportable as a CSV ledger. Swapping the base URL is the whole integration.
It also hosts three reduced-refusal models directly, aimed at authorized security testing and model evaluation: Qwen3.6-35B-A3B, Qwen3.8-27B and DeepSeek-V4-Flash, all at 128K context with published per-token rates from $1/M input. Prompts and outputs for these are not persisted, and access needs at least $50 in credit.
Provider list price plus a 3% routing fee, dropping to 1% past $500/month. No free tier; plans start at $5/month.
Pricing: Usage-based
What is Vynaris?
Vynaris is an OpenAI-compatible gateway that routes each request to the smallest model likely to handle it. Sending model: "auto" starts from a frontier model and downgrades when the router's eval evidence supports the swap; naming a model directly still gets it right-sized. The service is labelled early beta.
How it works
The base URL is https://api.vynaris.com/v1 for OpenAI-shaped clients, or https://api.vynaris.com for the Anthropic SDK. Swapping the base URL is the whole integration; prompts and tool definitions stay as they are. Documented setups cover Claude Code, Cursor, OpenClaw and Pi.
Every response returns a receipt in the headers naming the model that actually served the request, the provider's cost, the Vynaris fee and the final charge. The same data exports as a CSV ledger, which is the part that separates it from a plain proxy: the routing decision is auditable per request rather than taken on trust.
Hosted reduced-refusal models
Alongside the routed providers, Vynaris hosts three of its own models on 128K context, selectable by ID in any OpenAI-compatible request:
- vynaris/qwen3.6-35b-a3b-uncensored — $1.00 input / $5.00 output per 1M tokens
- vynaris/qwen3.8-27b-uncensored — $1.00 input / $7.00 output per 1M tokens
- vynaris/deepseek-v4-flash-uncensored — $2.00 input / $11.00 output per 1M tokens
Vynaris positions these for lawful, authorized red teaming, cyber defense and model evaluation, and publishes prohibited-use terms alongside them. Access requires a $50 balance.
Pricing
Routed requests bill at the provider's list price plus a 3% routing fee, dropping to 1% once monthly usage passes $500. There is no free tier and no trial: the cheapest way to start is the $5/month plan, which converts to API credit, or a $50 prepaid top-up. Credit rolls over and requests stop at a zero balance rather than incurring overages.
Who it is for
Teams running agent workloads where the same prompt does not need a frontier model every time, and who want per-request evidence of what a swap cost or saved. The terms state Vynaris is operated by a sole proprietor based in India, with no uptime SLA on self-serve plans, which is worth weighing for production traffic.
Vynaris Alternatives
Explore 122 products in the Inference APIs category. View all Vynaris alternatives.
2kw.ai
EU-hosted AI integration platform combining a provider gateway, document extraction, evals and cost observability
AISIX
Open-source AI gateway in Rust with one OpenAI-compatible API across 100+ LLM providers
AI Gateway HQ
LLM gateway built around spend limits enforced before a request reaches a provider
LLM Tech
EU inference provider serving Qwen3.8-27B from dedicated Helsinki GPUs it rents and operates itself, with zero data r...

NanoGPT
One OpenAI-compatible API for 600+ models, with text billed at provider list prices
Also listed in
Work on Vynaris? Feature it at the top of Inference APIs.
Is your product missing?