Inceptron
EU-hosted LLM inference with an in-house compiler: serverless open-weight model APIs and dedicated GPU deployments
Inceptron is an EU-hosted inference platform run by Inceptron AB in Lund, Sweden. It serves open-weight models over an OpenAI-compatible API and runs dedicated GPU deployments for custom or fine-tuned checkpoints.
An in-house compiler fuses graphs, auto-tunes kernels and plans memory for the target GPU. Serverless models include GLM-5.3, Kimi K2.6 and DeepSeek-V4 Flash. Customer content is processed only in the EU/EEA, and prompts are not stored by default.
Serverless is billed per token. Dedicated H100, H200 and B200 deployments cost $3, $5 and $8 per hour.
Pricing: Per token (serverless), hourly per GPU (dedicated)
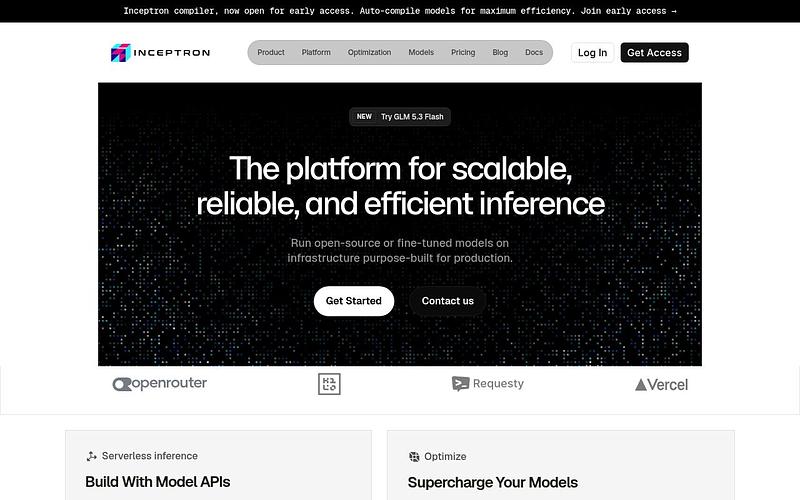
Inceptron prices by model
Per 1M tokens, read off Inceptron's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| GLM 5.3 | $1.40 | $0.26 | $4.40 | 15 Oct 2026 | Excl. taxes. The API model list reports lower figures ($0.55/$2.20); the models page is recorded. |
| GLM 5.3 Flash | $0.15 | $0.07 | $0.50 | 15 Oct 2026 | Excl. taxes. The API model list reports $0.108/$0.55; the models page is recorded. |
Inceptron Alternatives
Explore 135 products in the Inference APIs category. View all Inceptron alternatives.

Heabsy
EU inference API on its own GPUs in the EEA, with zero data retention and OpenAI- and Anthropic-compatible endpoints.

DeepInfra
Run the top AI models using a simple API, pay per use. Low cost, scalable and production ready infrastructure.

Hetzner GPU Servers
Dedicated single-GPU servers with NVIDIA RTX PRO Blackwell cards, billed hourly, in Finland and Germany
TrustRoute
OpenAI-compatible LLM gateway hosted in Switzerland, with per-workload rules on which models data may reach
Xinference
Open-source inference engine for 300+ open models, plus a hosted API and managed GPUs served from Australia
Work on Inceptron? Feature it at the top of Inference APIs.
Is your product missing?