
OpenRelay
Per-token inference on open models and hourly GPU rental, served from a pooled network of GPU sites
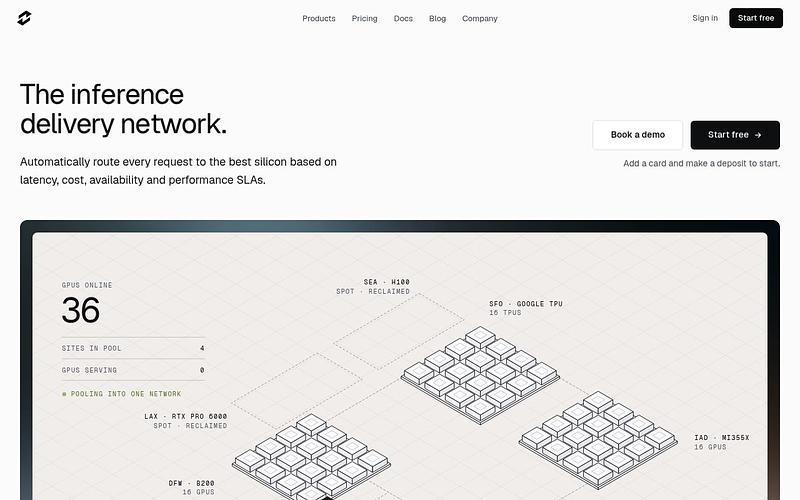
OpenRelay pools GPU capacity from many sites into one network and sells it two ways. Hosted inference runs open models such as GPT-OSS and Gemma behind one OpenAI- and Anthropic-compatible endpoint, billed per token, with async requests at 20 to 50% off and batch jobs at 50% off. Compute rents GPU VMs by the hour with no minimum.
GPT-OSS 120B is $0.15 in and $0.60 out per 1M tokens. GPUs start at $0.18/hr for an RTX 3090; an H100 SXM is $2.60/hr. Hardware owners can also join the network as suppliers.
Pricing: Per token usage
Choosing an inference API right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing an inference API right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
OpenRelay prices by model
Per 1M tokens, read off OpenRelay's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| gpt-oss-120b | $0.15 | $0.015 | $0.60 | 12 Nov 2026 | |
| gpt-oss-20b | $0.05 | $0.005 | $0.20 | 12 Nov 2026 |
OpenRelay Alternatives
Explore 164 products in the Inference APIs category. View all OpenRelay alternatives.

DeepInfra
Run the top AI models using a simple API, pay per use. Low cost, scalable and production ready infrastructure.
LibertAI
Decentralized, privacy-first inference API running open-source LLMs in trusted execution environments
Inceptron
EU-hosted LLM inference with an in-house compiler: serverless open-weight model APIs and dedicated GPU deployments
Synap
OpenAI-compatible API for open-weight Qwen models, served by a pool of GPUs that owners contribute


Wiro AI
One API for image, video, audio and LLM models, billed per run from a prepaid balance
Work on OpenRelay? Feature it at the top of Inference APIs.
Is your product missing?