Varion
OpenAI-compatible proxy that trims LLM token usage before requests reach your provider
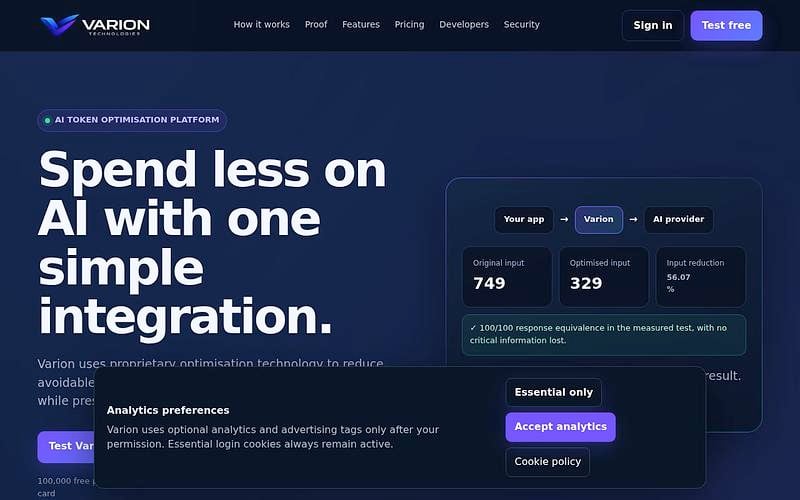
Varion is an OpenAI-compatible proxy that sits in front of LLM providers and reduces token usage before a request goes out. It compacts conversation history, prunes unused tool schemas, and caches exact-match duplicate requests, while passing through required context and instructions unchanged.
Integration is a base URL and key swap for any OpenAI SDK client. Varion adds a benchmark header on responses so teams can verify actual token savings rather than take the reduction on faith, plus a browser-based Test Lab and CLI/Python/Node clients for trying it before wiring it into an app.
The company also runs Varion Compute, a metered inference-efficiency service in commercial early access: it runs a workload on NVIDIA A40 GPUs and reports measured energy and throughput deltas against an unoptimized baseline, with validated results published per model (36.4% lower energy per token and 131.4% higher throughput on Qwen 2.5 1.5B, smaller models tested separately). 10 free GPU-hours for metered testing, no card required.
Pricing for the proxy is prepaid token-processing packages from EUR 19/month (Starter, 10M tokens) through Growth, Business, and Scale tiers. Provider costs are billed separately by the underlying LLM provider. New verified users get a free processing allowance to test with.
Pricing: Usage-based
Choosing an LLM gateway right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing an LLM gateway right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Varion Alternatives
Explore 150 products in the Inference APIs category. View all Varion alternatives.
2kw.ai
EU-hosted AI integration platform combining a provider gateway, document extraction, evals and cost observability
AISIX
Open-source AI gateway in Rust with one OpenAI-compatible API across 100+ LLM providers
AI Gateway HQ
LLM gateway built around spend limits enforced before a request reaches a provider

LLM Tech
EU inference provider serving Qwen3.8-27B from dedicated Helsinki GPUs it rents and operates itself, with zero data r...

NanoGPT
One OpenAI-compatible API for 600+ models, with text billed at provider list prices
Work on Varion? Feature it at the top of Inference APIs.
Is your product missing?