Coral Bricks
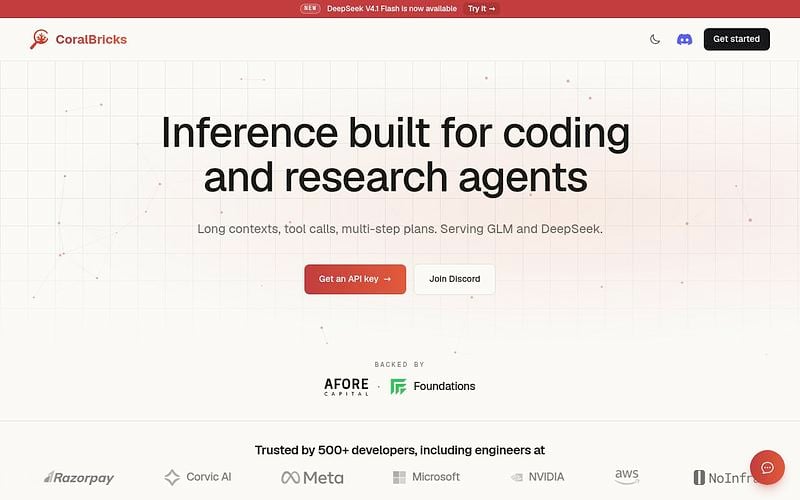
OpenAI-compatible inference for coding and research agents, serving GLM and DeepSeek with free cached reads.
Coral Bricks is a hosted inference API tuned for agent workloads: long contexts, tool calls and multi-step plans. It serves GLM 5.3, GLM 5.3 Flash and DeepSeek V4.1 Flash at FP4 precision with 1M-token context, and speaks both Chat Completions and the Responses API.
Cache writes bill once at up to 1.5x the input rate and cached reads are free. GLM 5.3 Flash starts at $0.15 per 1M input tokens. Setup guides cover OpenCode, Codex CLI, GitHub Copilot and Cursor, and dedicated capacity in your own VPC is available.
Pricing: Per token usage
Coral Bricks prices by model
Per 1M tokens, read off Coral Bricks's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| DeepSeek V4.1 Flash | $0.30 | $0.00 | $1.20 | 29 Sep 2026 | Listed as deepseek-v4.1-flash-fast-fp4 (MXFP4) |
| GLM 5.3 | $1.12 | $0.00 | $4.40 | 29 Sep 2026 | Promotional price, 20% off list $1.40 input; listed as glm-5.3-fp4 (NVFP4) |
| GLM 5.3 Flash | $0.15 | $0.00 | $0.50 | 29 Sep 2026 | Listed as glm-5.3-flash-fp4 (NVFP4) |
Coral Bricks Alternatives
Explore 109 products in the Inference APIs category. View all Coral Bricks alternatives.

CheapestInference
Flat-rate unlimited inference on open-weight models, sold in daily 8-hour windows

DeepInfra
Run the top AI models using a simple API, pay per use. Low cost, scalable and production ready infrastructure.

Heabsy
EU inference API on its own GPUs in the EEA, with zero data retention and OpenAI- and Anthropic-compatible endpoints.

Work on Coral Bricks? Feature it at the top of Inference APIs.
Is your product missing?