
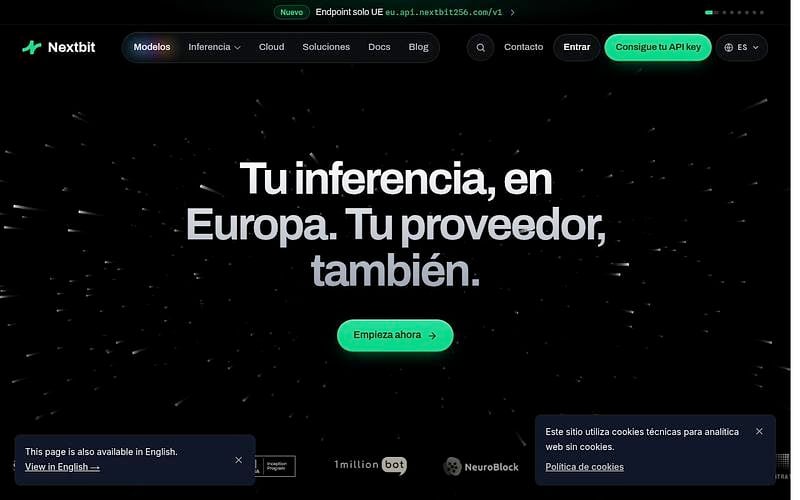
Nextbit
EU-hosted inference for open models over an OpenAI and Anthropic compatible API, plus dedicated endpoints and GPU cloud
Nextbit is a Spanish inference provider (NEXTBIT 256, S.L., Valencia) that serves open-weight models such as DeepSeek, Qwen, Gemma and GLM from its own hardware in Spain. The API is compatible with OpenAI and Anthropic clients and is billed per token with no minimums. A separate endpoint keeps requests inside the EU.
It also sells dedicated endpoints at a fixed monthly fee and GPU rental by SSH, including VMs for agents that run code.
Pricing: Per token usage
Choosing an inference API right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Choosing an inference API right now?
One click, anonymous. Helps us know our visitors.
Thanks, that helps.
Nextbit prices by model
Per 1M tokens, read off Nextbit's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| DeepSeek V4.1 Flash | $0.21 | $0.004 | $0.84 | 6 Nov 2026 | |
| GLM 5.3 Flash | $0.12 | $0.03 | $0.45 | 6 Nov 2026 |
Nextbit Alternatives
Explore 160 products in the Inference APIs category. View all Nextbit alternatives.

DeepInfra
Run the top AI models using a simple API, pay per use. Low cost, scalable and production ready infrastructure.



Mistral
Use models in a few clicks with our platform. Download our open models for deep access.
Work on Nextbit? Feature it at the top of Inference APIs.
Is your product missing?