
Aurora Inference
OpenAI-compatible API for open-weight models, with in-region deployment on reserved capacity
Aurora Inference serves open-weight models, including DeepSeek V4.1 Flash, GLM 5.2 and Kimi K3, through a single OpenAI-compatible endpoint. Metered per-token access has no commitment or minimum, and prompt and output content is not stored, logged or used for training.
Reserved capacity keeps prompts, outputs and weights in a chosen region across North America, Europe, the Nordics, the Middle East and APAC. Cached input is priced separately, from $0.006/1M tokens on DeepSeek V4.1 Flash. Aurora is run by Aurora Infrastructure EU in Kraków, Poland.
Pricing: Per token usage
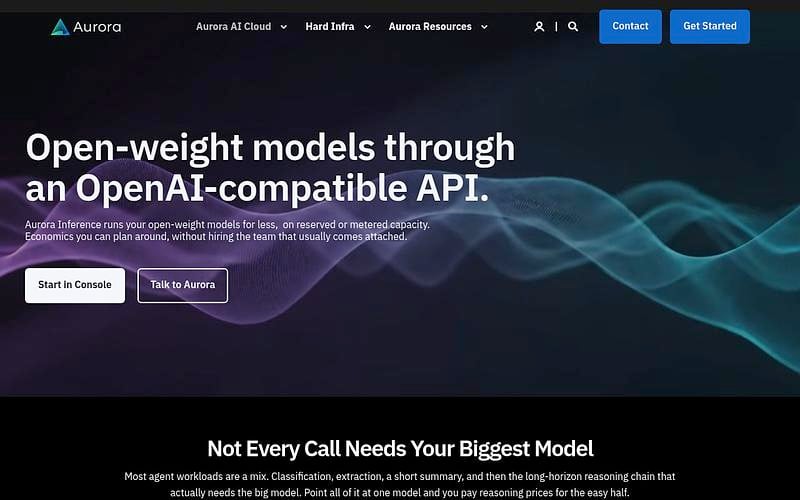
Aurora Inference prices by model
Per 1M tokens, read off Aurora Inference's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| DeepSeek V4 Pro | $1.00 | $0.10 | $2.00 | 25 Sep 2026 | Listed as deepseek/deepseek-v4-pro |
| DeepSeek V4.1 Flash | $0.20 | $0.006 | $0.60 | 25 Sep 2026 | Listed as deepseek/deepseek-v4-flash |
| Kimi K3 | $2.85 | $0.29 | $14.25 | 25 Sep 2026 |
Aurora Inference Alternatives
Explore 126 products in the Inference APIs category. View all Aurora Inference alternatives.

Heabsy
EU inference API on its own GPUs in the EEA, with zero data retention and OpenAI- and Anthropic-compatible endpoints.

DeepInfra
Run the top AI models using a simple API, pay per use. Low cost, scalable and production ready infrastructure.

TypeSafe Jev
Hosted decision model that returns typed choices, scores and yes/no answers with calibrated confidence.
Laya
Open-source multilingual decision model: typed choices, scores and yes/no answers in one forward pass.
Work on Aurora Inference? Feature it at the top of Inference APIs.
Is your product missing?